Hengwei Bian

01

About

👋 Hey there!

I’m currently a Machine Learning Engineer at ByteDance. My work focuses on building agents and the harnesses around them.

I received my M.S. from Carnegie Mellon University (CMU), where I worked with Prof. Min Xu at XuLab. Before that, I completed my undergraduate studies at Nanyang Technological University (NTU) and worked with Prof. Ziwei Liu in S-Lab. I also continue to collaborate with Dr. Liang Pan on several research projects.

My research interests include 3D generation and world models.

Outside of work, I enjoy singing—skill level aside—and trying out new hobbies. My recent experiments include Black Myth: Wukong, guitar, and indoor bouldering.

I also have an especially cute dog named Mocha. You can find more of Mocha on Instagram.

I’m always up for an interesting conversation, a brainstorming session, or a potential collaboration—feel free to connect!

02

Publications
DynamicCity project teaser

ICLR 2025 Spotlight

DynamicCity: Large-Scale 4D Occupancy Generation from Dynamic Scenes

Bian, Hengwei and Kong, Lingdong and Xie, Haozhe and Pan, Liang and Qiao, Yu and Liu, Ziwei

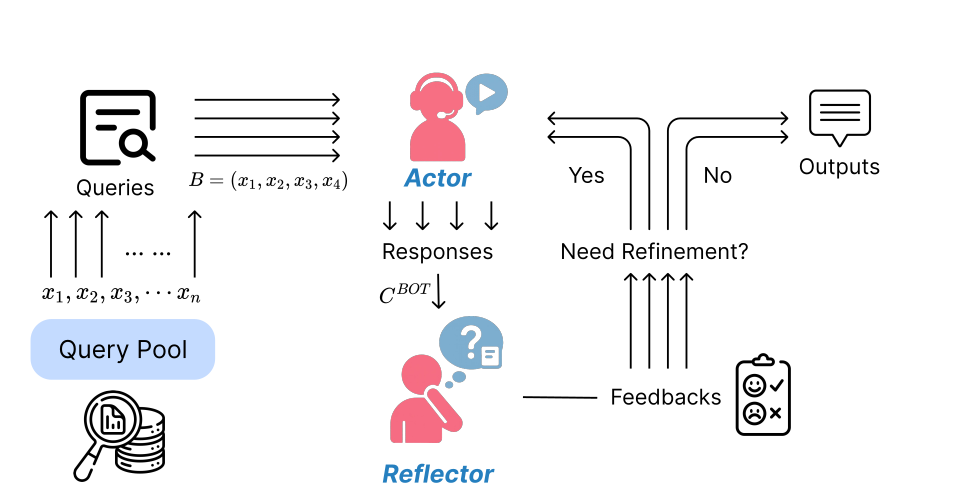
Batch-of-Thought reflection framework

EMNLP 2026

Batch-of-Thought: Cross-Instance Learning for Enhanced LLM Reasoning

Xuan Yang, Furong Jia, Roy Xie, Xiong Xi, Hengwei Bian, Jian Li, and Monica Agrawal

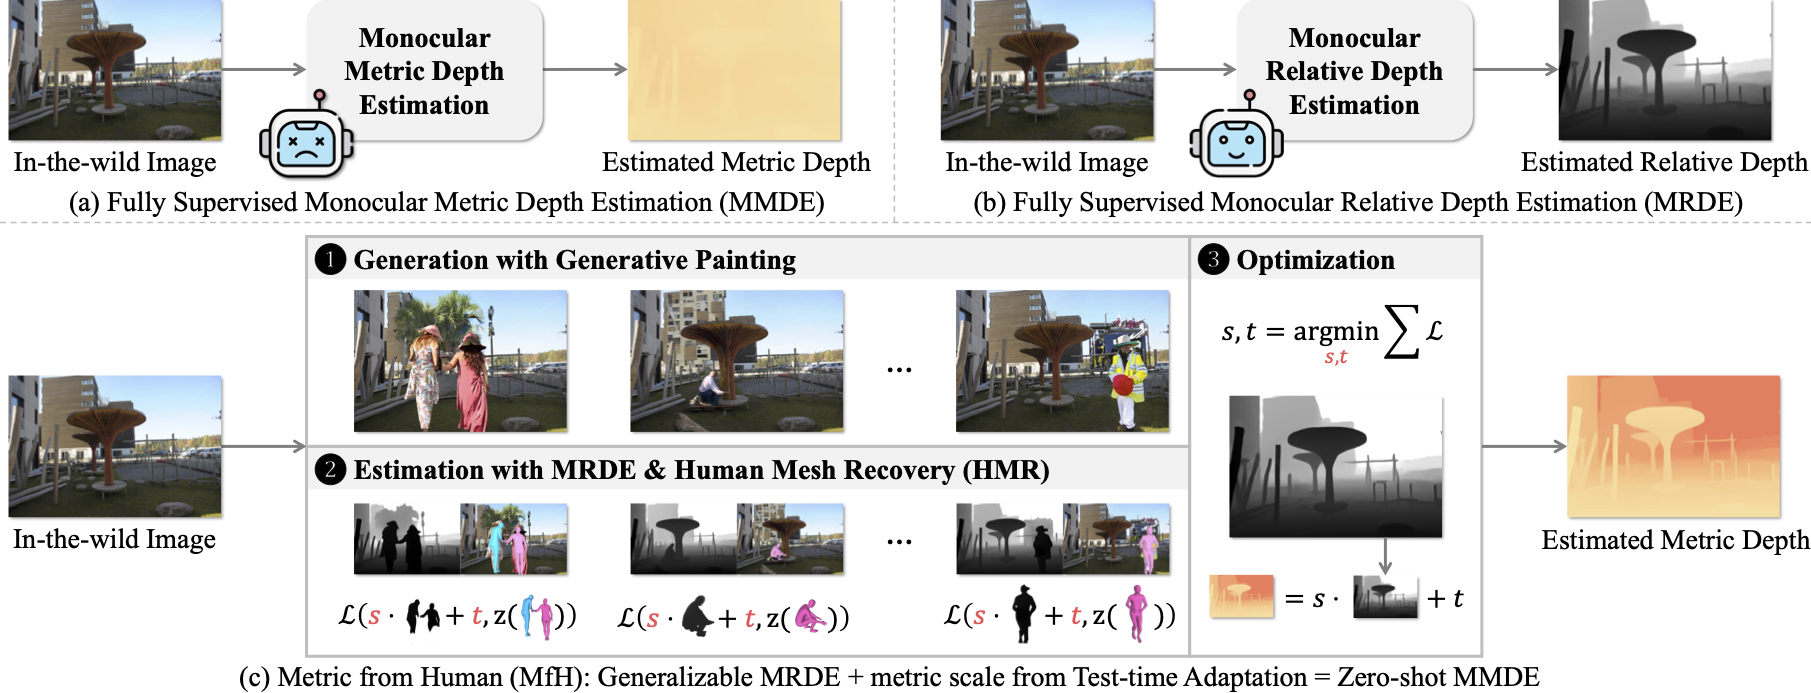
Metric from Human project teaser

NeurIPS 2024

Metric from Human: Zero-shot Monocular Metric Depth Estimation via Test-time Adaptation

Zhao, Yizhou and Bian, Hengwei and Chen, Kaihua and Ji, Pengliang and Qu, Liao and Lin, Shao-yu and Yu, Weichen and Li, Haoran and Chen, Hao and Shen, Jun and Raj, Bhiksha and Xu, Min

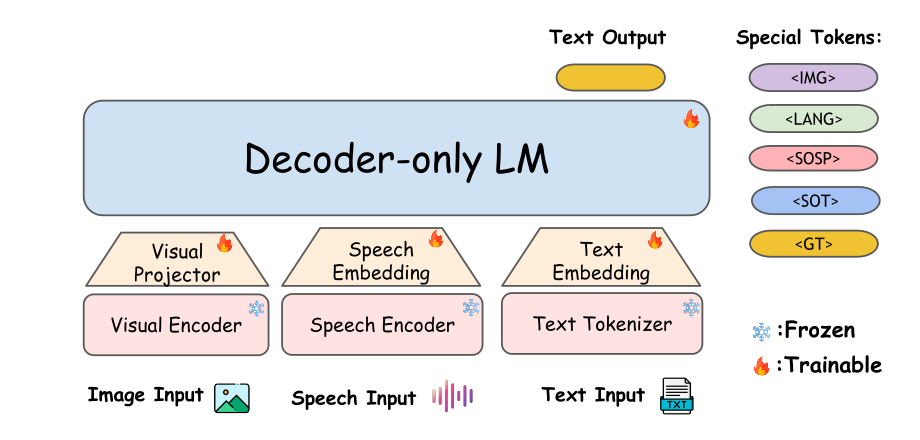
SynesLM architecture overview

Interspeech 2024 · Syndata4genai Workshop

SynesLM: A Unified Approach for Audio-visual Speech Recognition and Translation via Language Model and Synthetic Data
Lu, Yichen and Song, Jiaqi and Chang, Xuankai and Bian, Hengwei and Maiti, Soumi and Watanabe, Shinji

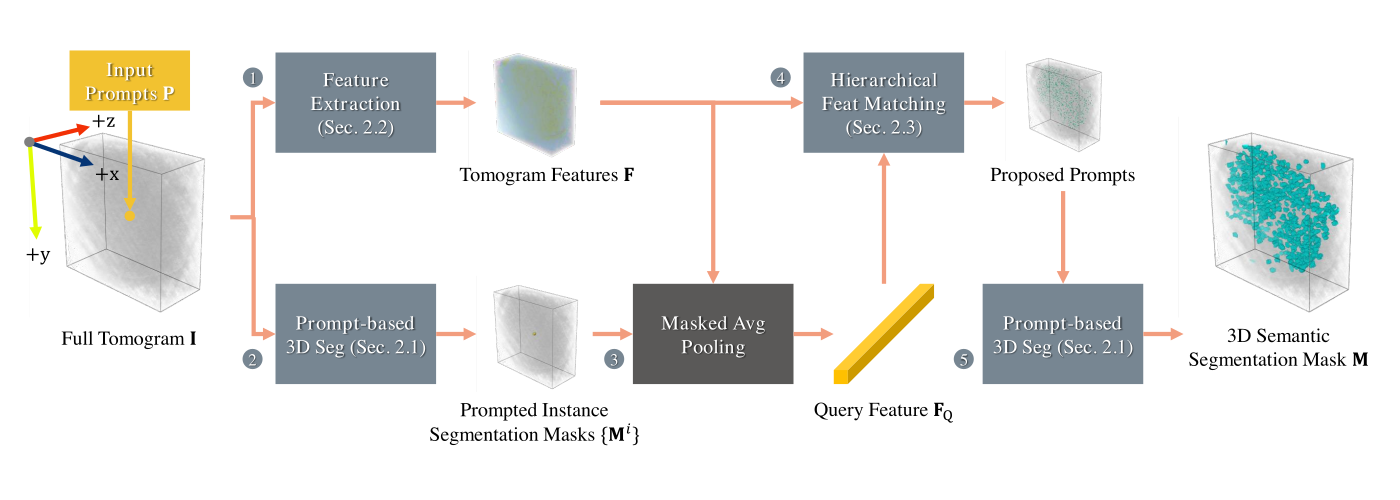
CryoSAM framework overview

MICCAI 2024

CryoSAM: Training-free CryoET Tomogram Segmentation with Foundation Models

Zhao, Yizhou and Bian, Hengwei and Mu, Michael and Uddin, Mostofa R. and Li, Zhenyang and Li, Xiang and Wang, Tianyang and Xu, Min

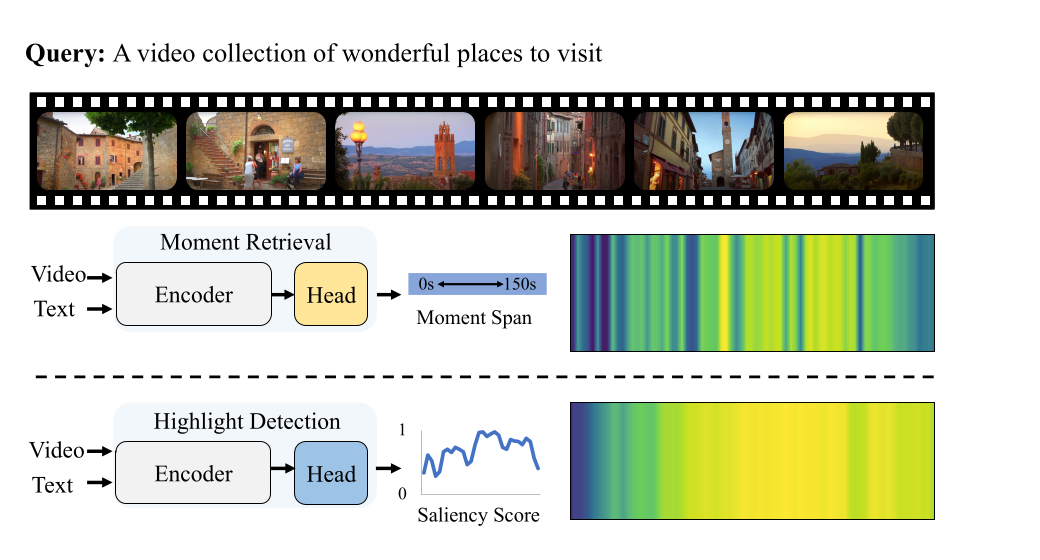
UVCOM overview of moment retrieval and highlight detection

CVPR 2024

Bridging the Gap: A Unified Video Comprehension Framework for Moment Retrieval and Highlight Detection

Xiao, Yicheng and Luo, Zhuoyan and Liu, Yong and Ma, Yue and Bian, Hengwei and Ji, Yatai and Yang, Yujiu and Li, Xiu

03

Contact